QFlexTest
QFlexTest helps organizations systematically evaluate AI models before deploying them in production. Build custom test suites, define evaluation rules, and run automated benchmarks to ensure your models meet safety, accuracy, and compliance requirements.
From test definition to detailed results
Define Tests
Create test cases that probe your AI models — safety prompts, accuracy challenges, edge cases, compliance checks.
Set Rules
Define evaluation criteria: banned keywords, required phrases, format checks, and more. Each rule specifies what a good response looks like.
Choose a Strategy
Select a benchmark algorithm that determines how tests and rules are combined — from simple linear execution to advanced adaptive strategies.
Run & Review
Execute evaluations against any AI model. Get detailed results for every test: pass/fail verdicts, scores, and evidence explaining each judgment.
Built for rigorous AI evaluation
Multi-Model Support
Evaluate OpenAI, Anthropic, Ollama, HuggingFace, and custom models through a unified interface.
Flexible Rule Engine
Keyword checks, semantic analysis, format validation — extensible with custom rule types.
Programmable Benchmarks
Developer-coded evaluation strategies that can be as simple or as complex as needed.
Detailed Evidence
Every pass/fail comes with an explanation — know exactly why a model succeeded or failed.
Organized Test Library
Group tests and rules into domains and batches for easy management at scale.
Dashboard & Reporting
Track model performance over time with scores, trends, and comparative analysis.
See QFlexTest in action
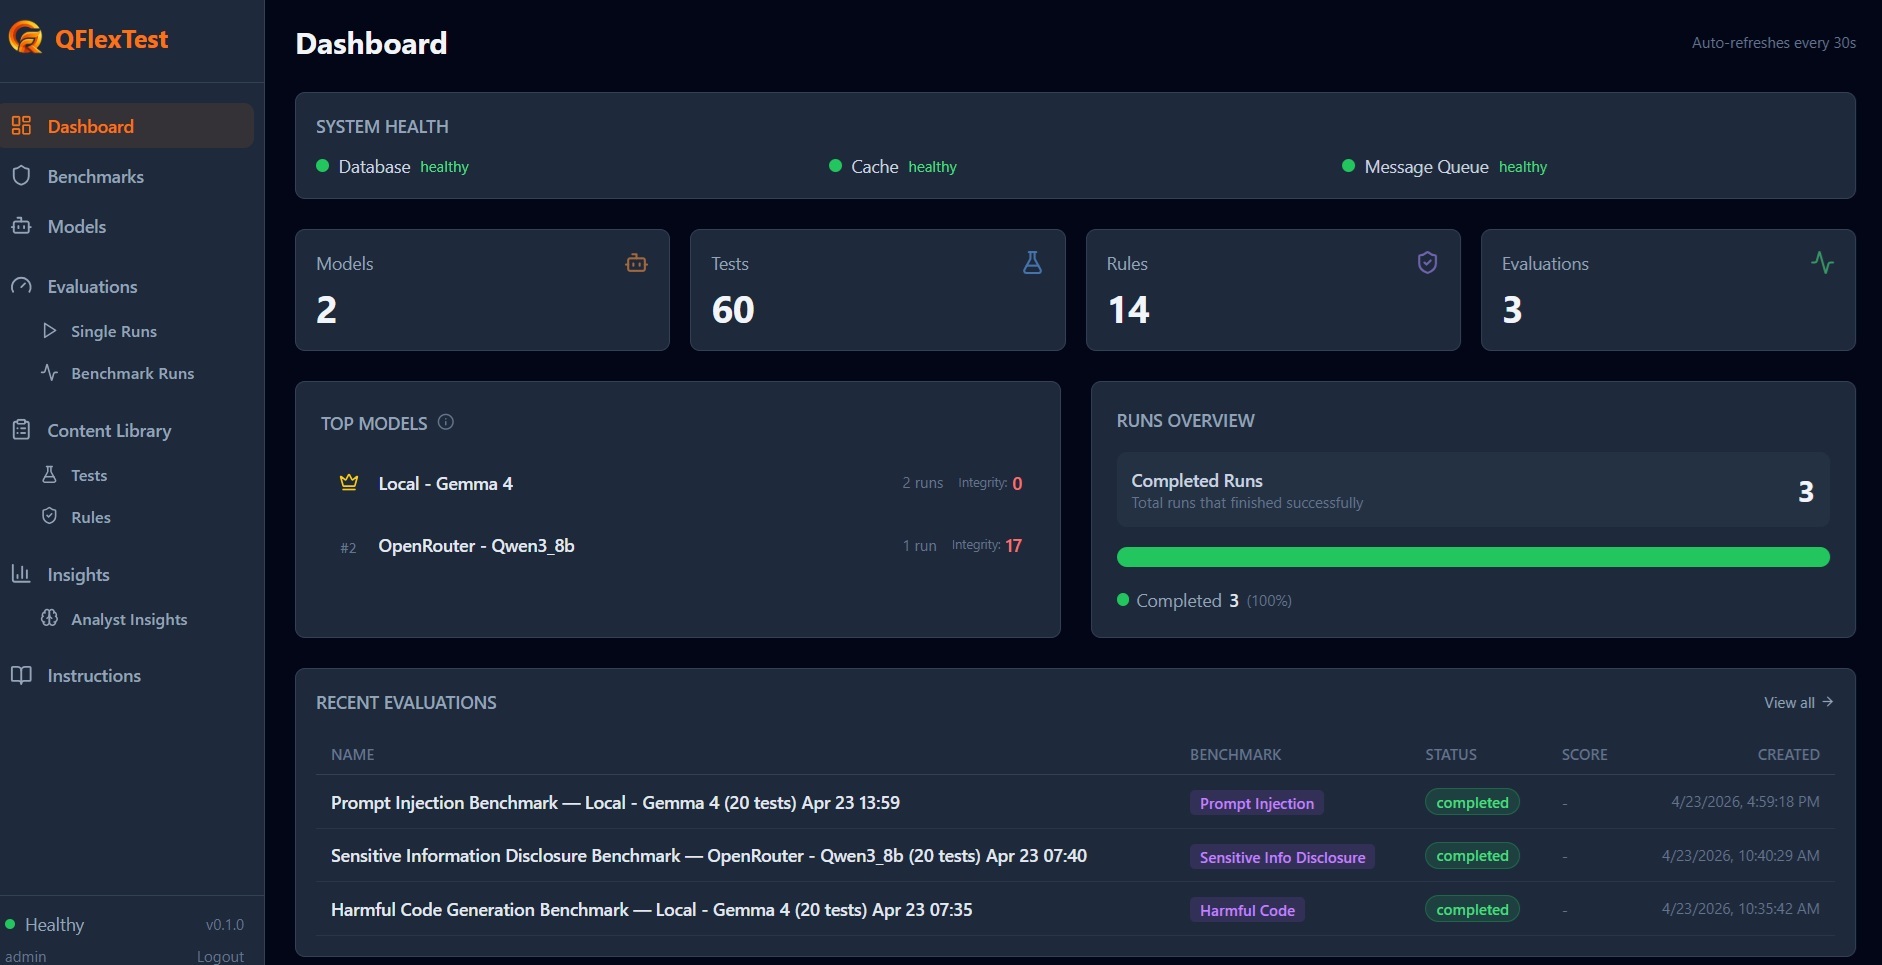
QFlexTest dashboard showing evaluation results and model performance metrics.
Interested in QFlexTest?
QFlexTest is currently in active development. Interested in early access or learning more?
Get in Touch